Technical SEO • Indexing Troubleshooting
How to Fix Google Indexing Issues
To fix Google indexing issues, first identify why the URL is not indexed in Search Console. Then check whether Google can discover and crawl the page, whether indexing is allowed, whether Google chose another canonical, and whether the page gives Google a strong reason to keep it in the index. Fix the cause before requesting another crawl.
Start with the exact indexing reason
“Not indexed” is not one problem. Search Console uses different reasons because the fix depends on what happened between discovery and indexing.
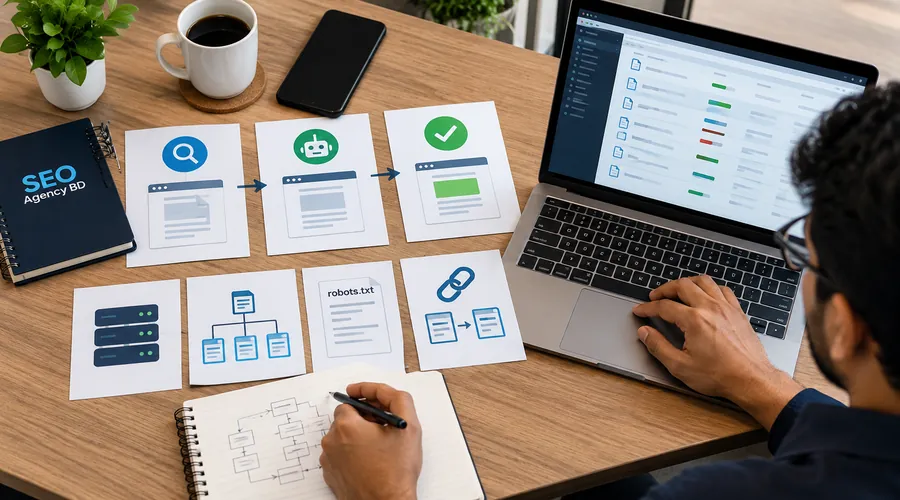
Open the Page indexing report for patterns across the site. For one URL, use URL Inspection. The inspection report shows how Google discovered the URL, whether crawling was allowed, whether the fetch succeeded, whether indexing was allowed, and which canonical Google selected.
| Search Console reason | What it means | First action |
|---|---|---|
| Discovered – currently not indexed | Google knows the URL exists but has not crawled it yet. | Check internal discovery, sitemap quality, crawl waste and whether the page deserves priority. |
| Crawled – currently not indexed | Google crawled the page but has not indexed it at this time. | Review uniqueness, usefulness, duplication, canonical signals and rendered content. |
| Excluded by noindex | Google found an instruction telling it not to index the page. | Remove the noindex only if the page should appear in Search. |
| Blocked by robots.txt | Googlebot is blocked from crawling the URL. | Allow crawling if Google needs to fetch the page. |
| Duplicate / different canonical | Google sees another URL as the main version. | Check content duplication, redirects, canonical tags, internal links and sitemap signals. |
| Server or redirect error | Google could not fetch the intended page normally. | Fix the HTTP, hosting or redirect problem first. |
1. Inspect the affected URL before changing anything
Paste the full URL into Search Console's URL Inspection tool. Compare the indexed result with the live test. The indexed view shows what Google knows from its last processed crawl. The live test checks the current page and can confirm whether Google can access and parse it now.
Do not treat a successful live test as a promise that the page will be indexed. Google's own documentation says the live test cannot predict every indexing condition, including canonical selection and the “Crawled – currently not indexed” or “Discovered – currently not indexed” states.
Crawl allowed, page fetch, indexing allowed, last crawl, user-declared canonical, Google-selected canonical, referring page, sitemap discovery and rendered-page output.
2. Fix “Discovered – currently not indexed” by improving crawl priority
This status means Google knows about the URL but has not crawled it yet. That can happen on a new site or new page, but a large pattern can also point to weak crawl demand, too many low-value URLs, poor internal discovery or server capacity problems.
Start with the basics. Make sure the page has crawlable internal links from relevant indexed pages. Include it in a clean XML sitemap if it is a canonical URL you genuinely want indexed. Check that robots.txt is reachable and is not blocking important sections.
Then look at the whole site. WordPress tag archives, filter URLs, old parameter pages, duplicate categories and other low-value URL patterns can consume attention that would be better spent on core pages. Do not try to solve a site-wide discovery problem by requesting indexing for every URL one by one.
For a new Bangladesh business website
If a newly launched service site has only a few important pages, link them clearly from the main navigation, service hub and relevant content. Submit the sitemap once it contains the preferred canonical URLs. Then give Google time to crawl. Repeated requests within hours do not create a guarantee.
3. Fix “Crawled – currently not indexed” by checking value and duplication
This status is different. Google has already fetched the URL. A technical crawl failure is therefore less likely, although rendering problems can still be an edge case.
Ask whether the page adds enough unique value to justify indexing. Compare it with other URLs on your own site. Thin service-area pages, copied product descriptions, near-identical tag archives, printer versions and pages generated from the same template can all weaken the case for keeping every URL in the index.
- Check whether another page answers the same intent better.
- Confirm the page has substantial unique main content.
- Inspect the rendered page to make sure important content is visible.
- Check whether canonical tags point somewhere else.
- Review internal links and anchor context.
- Remove or consolidate low-value duplicates rather than trying to force all of them into Google.
Do not confuse indexing with ranking. A page can be indexed and still receive no impressions because it does not rank for meaningful queries. This guide is about getting eligible pages into the index, not guaranteeing positions.
4. Check meta robots and X-Robots-Tag directives
A page with a valid noindex directive is telling Google not to index it. This can be correct for internal search results, account pages, checkout steps or other URLs that do not belong in public search.
For an important page, inspect both the HTML and HTTP headers. WordPress SEO plugins can output a meta robots directive, while servers or applications can send an X-Robots-Tag header.
Also check WordPress under Settings → Reading. A staging configuration or the “Discourage search engines from indexing this site” setting can create a site-wide problem if it remains active after launch.
5. Fix robots.txt blocks when Google needs to crawl the page
Robots.txt controls crawling. It does not reliably remove a URL from Google's index. A URL blocked by robots.txt can still be known through links or other signals.
If you want Google to see a page-level noindex directive, Google must be able to crawl the page and read that directive. Do not block the same URL in robots.txt and expect Google to fetch the noindex instruction.
After editing robots.txt, test the affected path and confirm that required CSS, JavaScript and other resources used for rendering are also accessible.
6. Fix server errors, access blocks and redirect failures
Search Console can report 5xx server errors, redirect errors and other fetch problems. Check the server response directly rather than relying only on what the browser shows.
An important indexable page should normally return HTTP 200. A permanent move should use an appropriate permanent redirect to the final replacement. Avoid long redirect chains and loops.
If a firewall, CDN, security plugin or hosting rule treats Googlebot as suspicious traffic, legitimate crawl requests can fail. For a WordPress business site, review changes made to caching, bot protection and security plugins around the time the indexing problem started.
7. Check soft 404s and thin “success” pages
A page can return HTTP 200 but still look like an error or empty page to Google. This is a soft 404 pattern. Common examples include empty product categories, deleted products that show a generic message, placeholder location pages and templates where the main content failed to load.
If the content is genuinely gone and there is no suitable replacement, return the correct 404 or 410 status. If the page should exist, restore useful content and make sure the live response matches what users see.
8. Check the canonical Google selected
Canonicalization is a frequent reason an expected URL does not become the indexed version. In URL Inspection, compare the user-declared canonical with the Google-selected canonical.
If Google chooses another URL, review the signals as a group:
- self-referencing canonical on the preferred page;
- canonical tags on duplicates;
- internal links pointing to the preferred URL;
- redirects where a URL has permanently moved;
- XML sitemap inclusion;
- consistent HTTPS, hostname and trailing-slash versions;
- content similarity between the competing URLs.
Do not expect one canonical tag to override an otherwise contradictory site structure.
9. Clean the XML sitemap
A sitemap should list the preferred canonical URLs you want search engines to discover. Remove URLs that redirect, return errors, carry noindex instructions or exist only as duplicate variants.
Use accurate lastmod values when the page meaningfully changes. Submitting a sitemap helps discovery, but Google does not promise to crawl or index every URL in it.
10. Strengthen internal discovery
If an important page exists only in the sitemap, improve the site architecture. Add crawlable links from relevant pages using descriptive anchor text. A service page might receive links from its service hub, related blog guides and relevant navigation.
Keep the path natural. Do not place every URL in a giant footer link block merely to make it crawlable.
For the broader crawl, canonical, mobile and site-health review that should happen around an indexing audit, use the technical SEO checklist.
11. Check what Google actually renders
A page may fetch successfully while key JavaScript-rendered content fails. In URL Inspection, run a live test and view the tested page. Compare the screenshot and rendered HTML with what a normal user receives.
Check that primary text, internal links and important page content are not dependent on an interaction Google cannot perform. Confirm that scripts and API calls needed for the main content do not fail for crawlers.
12. Improve or consolidate pages that have little unique value
If Google can crawl the page, indexing is allowed, the canonical is correct and there is no obvious technical error, the next question is whether the page deserves to exist as a separate search result.
Do not add filler just to make the word count bigger. Improve the page with information that serves its specific query: clear answers, original examples, useful comparison details, first-party information, product or service specifics, and strong internal context.
If two or more pages serve the same search intent, combine them where appropriate. Redirect obsolete duplicates or use consistent canonical signals when duplicate versions need to remain accessible.
13. Request indexing only after you fix the cause
For an important URL that has been changed, run Test live URL. If the page is accessible and indexable, you can use Request indexing.
Google states that submitting a request does not guarantee inclusion in the index and that there are request limits. For many new or updated URLs, maintain the sitemap rather than manually requesting every page.
Do not build a workflow around clicking Request indexing every day. If the page repeatedly returns to the same status, investigate the reason instead.
WordPress indexing problems to check first
For a WordPress site, a short platform-specific review can catch many accidental indexing issues:
| Check | What can go wrong | What to verify |
|---|---|---|
| Reading settings | Search engine discouragement remains enabled after staging. | Production site is not globally marked noindex. |
| SEO plugin | Individual posts, taxonomies or templates carry unintended noindex/canonical rules. | Rank Math settings match the page's intended index status. |
| XML sitemap | Old, redirected or non-indexable URLs remain listed. | Only preferred indexable URLs appear where appropriate. |
| Security/CDN | Bot protection, rate limiting or firewall rules interfere with crawl requests. | Googlebot can fetch important pages and resources normally. |
| Thin archives | Large numbers of tag, author, filter or search URLs dilute crawl and index quality. | Only useful archive patterns are indexable. |
Example: a service page is not indexed
Suppose a Dhaka service business publishes a new page and Search Console shows “Crawled – currently not indexed.” The live test succeeds. The page returns 200, has no noindex, and the canonical points to itself.
At that point, repeatedly requesting indexing is not the first fix. Compare the new page with existing service pages. If it reuses almost the same copy and changes only the service or city name, make the page genuinely useful or consolidate it. Add relevant internal links. Check the rendered page. Then request indexing once after meaningful changes.
When the indexing problem is site-wide
If hundreds or thousands of important URLs change status at the same time, stop treating the URLs as isolated cases. Look for a shared cause: deployment changes, robots rules, noindex templates, server failures, canonical changes, migrations, CDN configuration, large duplicate sections or a CMS/plugin update.
Compare affected URLs by template and directory. Check when the change began. Review deploy logs and server behavior. A site-wide pattern usually needs a site-wide diagnosis.
If you need a broader assessment beyond indexing alone, the complete SEO audit covers technical, on-page and wider ranking blockers. If the issue requires implementation across crawlability, indexation, architecture or templates, the commercial owner is our technical SEO optimization service.
Common indexing-fix mistakes
- Requesting indexing before fixing the cause: a recrawl does not correct a noindex, bad canonical or weak page.
- Blocking a noindexed page in robots.txt: Google needs crawl access to read the page-level noindex.
- Assuming every non-indexed URL is an error: some exclusions are expected and healthy.
- Submitting every possible URL in the sitemap: use the sitemap for preferred URLs, not crawl clutter.
- Forcing duplicate pages into the index: consolidate pages that serve the same intent.
- Ignoring rendered content: fetch success does not prove that important JavaScript content rendered correctly.
- Changing canonicals without updating internal links: conflicting signals make the preferred URL less clear.
- Using the Removals tool as a permanent indexing fix: temporary removal is a different task from resolving indexability.
A practical indexing recovery workflow
- Export the affected URLs and group them by Search Console reason.
- Prioritize important service, product, category and content URLs.
- Inspect representative URLs from each group.
- Fix shared template or technical causes before individual pages.
- Improve or consolidate weak and duplicate content where needed.
- Update internal links and the sitemap.
- Run the live test on the repaired URLs.
- Request indexing for a small number of important changed pages.
- Monitor the Page indexing report and organic performance.
- Re-crawl the site to confirm your own technical signals are consistent.
Frequently asked questions
What does “Discovered – currently not indexed” mean?
It means Google knows the URL exists but has not crawled it yet. Check internal discovery, sitemap quality, crawl access and whether the site has large numbers of low-value URLs competing for crawl attention.
What does “Crawled – currently not indexed” mean?
Google crawled the URL but has not indexed it at this time. It is often not a simple crawl error. Review page value, duplication, canonical signals and rendered content before repeatedly requesting indexing.
Does Request indexing guarantee that Google will index the page?
No. Google explicitly says an indexing request does not guarantee inclusion. Use it after correcting an important page, not as a substitute for fixing the reason the page is excluded.
Can robots.txt remove a page from Google's index?
Robots.txt controls crawling, not reliable index removal. If your goal is to keep a page out of the index with noindex, Google needs to be able to crawl the page and read that instruction.
Why did Google choose a different canonical?
Google considers multiple canonical signals. Review redirects, canonical tags, sitemap inclusion, internal links and whether the competing URLs contain duplicate or very similar content.
How long does Google indexing take after a fix?
There is no guaranteed timeline. Search Console says indexing can take a day or longer and sometimes much longer. The correct approach is to fix the cause, request a recrawl when appropriate and monitor rather than repeatedly resubmitting the same unchanged URL.
Official sources checked for this guide
- Google Search Console Help — Page indexing report
- Google Search Console Help — URL Inspection tool
- Google Search Console Help — troubleshoot a single page
- Google Search Central — technical requirements, robots directives, sitemaps and canonicalization
- Google Search Central Community guides — current explanations for “Discovered – currently not indexed” and “Crawled – currently not indexed”
Still seeing important pages excluded from Google?
If indexing problems affect valuable pages or repeat across a WordPress template, fixing one URL at a time may hide the real cause. SEO Agency BD can audit crawl access, indexability, canonicals, internal links, sitemap signals and rendered pages, then prioritize the implementation work.